Fish Speech: free (or nearly free) AI voice cloning, an ElevenLabs alternative
Fish Speech is Fish Audio's open repository for text to speech (TTS) and voice cloning with models you can run on your own machine or on a rented GPU. Version 3.0 ships two models: Drama 3, the new flagship for multi-character scenes and long audio, and S2-Pro, the previous one, smaller and able to fit a consumer graphics card. Both clone a voice from a few seconds of reference audio.
We looked at it with one question in mind: how much does it cost you to get good voices for your videos, courses or app? We read the code, the docs and both licenses, and compared prices with ElevenLabs. Short version: there is a free option, a very cheap one, and a license catch you should know before using it in a business.
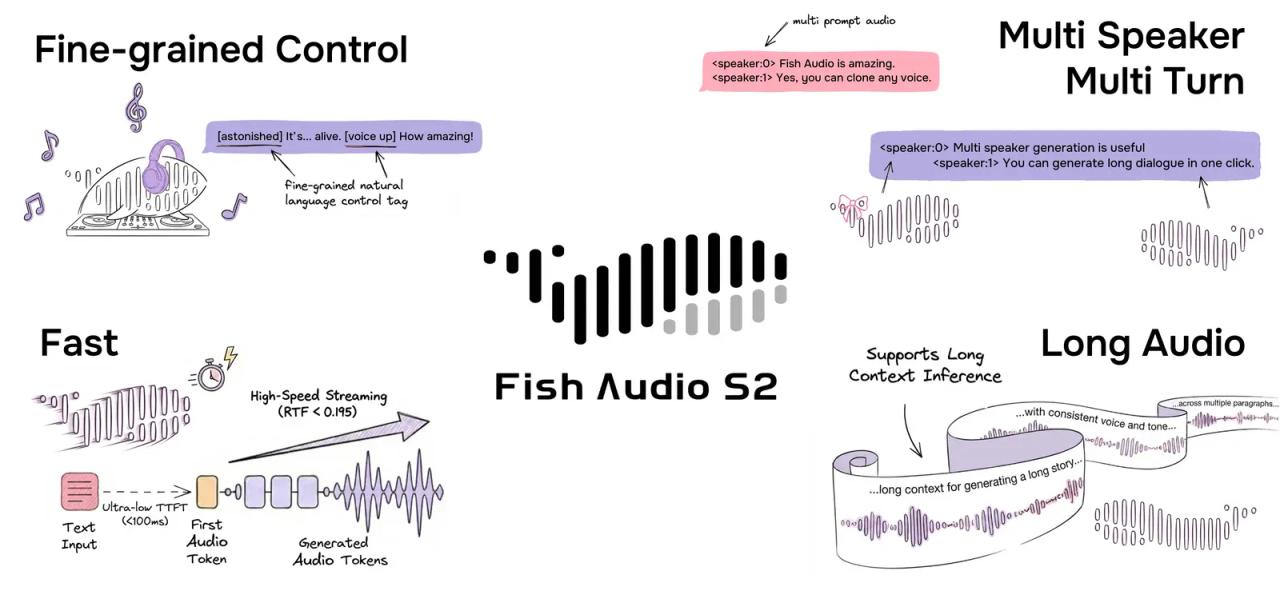
What Fish Speech is and who builds it
- Repository: github.com/fishaudio/fish-speech
- Version reviewed: 3.0.0 (
pyproject.toml), commit0f8a12efrom October 30, 2026. - Company: Fish Audio (39 AI, Inc.), which also sells the paid fish.audio platform.
- License: not MIT. The code and Drama 3 use the Fish Audio Community License v1.0 (October 13, 2026), and the S2-Pro weights stay under the Fish Audio Research License. We cover both below, because they decide whether you can make money with it.
- Stack: Python 3.12, PyTorch 2.8, its own HTTP server and a React web interface (*Awesome WebUI*) bundled in the Docker image.
Fish Audio publishes technical reports for Drama 3 (arXiv 2610.18010) and S2 (arXiv 2603.08823); the figures we quote come from those and from the README.
Drama 3 vs S2-Pro: what each model does
| S2-Pro | Drama 3 | |
|---|---|---|
| Size | 4B parameters | 35B mixture of experts, 3B active per token |
| Languages | 80+ | Same as S2 |
| Voice cloning | Yes, from 10-30 s of audio | Yes, with lower multilingual error rates |
| Emotion tags | `[pause]`, `[excited]`, `[whisper]`... | `[whisper]`, `[angry]`, `[laughing]`... with stronger emotion |
| Multiple speakers | Yes, with `speaker:N` tags | Yes, full scenes with up to 16 speakers |
| Edit one word in the audio | No | Yes ("Wednesday" → "Thursday" without regenerating) |
| Ask for another take ("softer, sadder") | No | Yes, multi-turn revision |
| Minimum hardware | 24 GB GPU or CPU | 48 GB NVIDIA GPU (FP8) |
| Weights license | Research (non-commercial) | Community (commercial, with limits) |
In practice, S2-Pro is the model to try at home and Drama 3 is the one that makes sense for real production: long narration, character dialogue, audiobooks or game voices. In the technical report, Drama 3 has a lower error rate than ElevenLabs v4 in English, Spanish, German and six other languages of the MiniMax Multilingual test set.
Both share the same command line and server: the model type is read from the checkpoint's config.json, so switching is just changing a path.
The license, in plain English
This is the most important part if you plan to use it in a business, because there are two different licenses depending on the model you load.
Drama 3 and the code: Fish Audio Community License
- Personal use, testing and research: free, no extra conditions.
- Commercial use: free while you and your affiliates make under 500,000 USD a year in total revenue, from all sources, not just audio. Once you cross it, you have 30 days to notify Fish Audio and a 90-day transition before you need a paid license.
- Agencies and freelancers: you can produce voiceovers, dubbing or audiobooks and deliver only the audio to clients of any size. If you install the model on a client's own systems instead, that client must also be under 500,000 USD.
- What you can't do without paying: run a text-to-speech service for third parties (an API, website or app whose main purpose is letting others generate speech or clone voices). Using speech inside your own product is fine: an assistant that talks, game characters or your app's narration.
- Obligations: show "Built with Fish Audio" on a related website, docs or about page, and include the license and a
NOTICEfile if you redistribute the model or code. - Always forbidden: imitating an identifiable person's voice without consent, impersonation to deceive, removing audio watermarks, and using the outputs to train another speech model.
- You own the output "to the extent permitted by applicable law".
S2-Pro: Fish Audio Research License
The S2-Pro weights keep the older license, which only allows research and non-commercial use (hobby, evaluation, testing). Any use tied to a product, a service or a company's internal operations needs a separate commercial license. If you want voices for a paid course or for ads, self-hosted S2-Pro is not an option.
One detail: on Hugging Face, the Drama 3 card text says Community License but its metadata still says Research License. The repository's LICENSE file, which names Drama 3 explicitly, is what counts; if you build a business on it, keep a copy of the version you accepted.
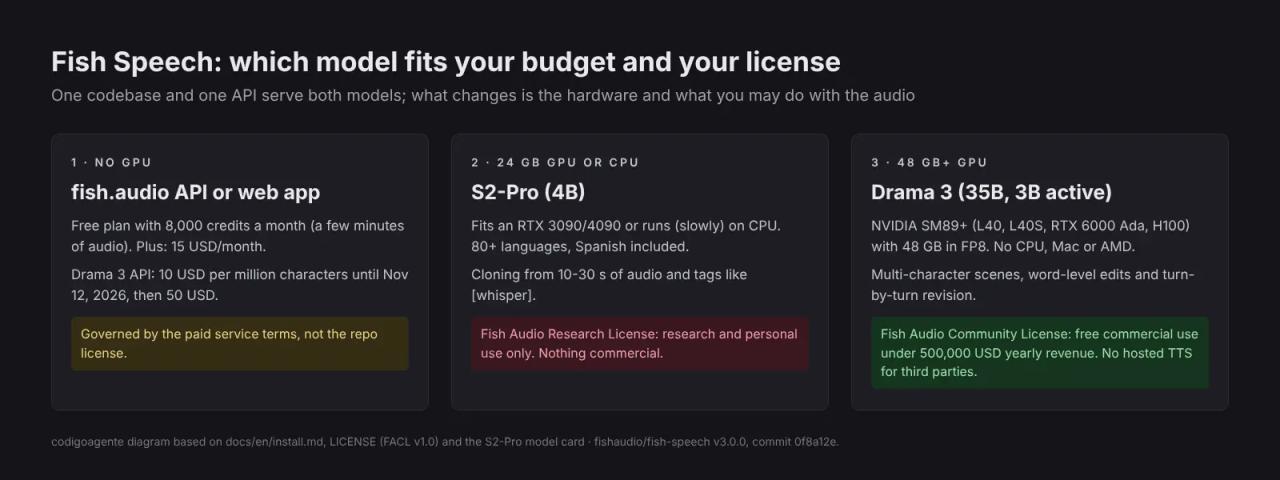
What you need to run it
| Model | GPU memory | Supported cards |
|---|---|---|
| Drama 3 | at least 48 GB (FP8) | NVIDIA only. To fit on a single card you need SM89 or newer (Ada or Hopper: L40, L40S, RTX 6000 Ada, H100). No CPU, Mac or AMD. |
| S2-Pro | 24 GB recommended | NVIDIA, CPU, AMD with ROCm (RDNA3/RDNA4) or Intel Arc |
The SM89 part comes from the code: the model's experts stay in FP8 only when every GPU has FP8 tensor cores (fp8_moe.py); on older cards such as an RTX A6000 or a 3090 they are dequantized to 16 bits and the model no longer fits one GPU, so you need several. OS: Linux or WSL on Windows.
In money terms:
- A 24 GB RTX 3090 or 4090 runs S2-Pro. If you already own one, the cost is electricity. Non-commercial use only.
- Drama 3 at home needs a 48 GB workstation card that costs thousands of dollars. For most people the sensible path is renting a GPU by the hour: on RunPod a 48 GB L40 was about 0.82 USD per hour and an L40S 1.09 USD on November 5, 2026.
- Speed: Fish Audio measures Drama 3 on an H200 at an RTF of 0.131 for a single stream, about seven times faster than real time, with first audio in under 90 ms. An L40 will be slower; we did not measure it.
Install Fish Speech with Docker
The shortest path is the official image with the server and web UI. Download the weights first (you need the Hugging Face CLI), then start the container:
pip install -U "huggingface_hub[cli]"
hf download fishaudio/s2-pro --local-dir checkpoints/s2-pro
hf download fishaudio/drama-3 --local-dir checkpoints/drama-3
Download S2-Pro even if you only want Drama 3: when the Drama 3 folder has no codec.pth, the server uses checkpoints/s2-pro/codec.pth.
Drama 3 on a single SM89+ GPU:
docker run --gpus device=0 \
    -v ./checkpoints:/app/checkpoints \
    -e LLAMA_CHECKPOINT_PATH=checkpoints/drama-3 \
    -p 8080:8080 \
    fishaudio/fish-speech:server-cuda
S2-Pro:
docker run --gpus all \
    -v ./checkpoints:/app/checkpoints \
    -e LLAMA_CHECKPOINT_PATH=checkpoints/s2-pro \
    -e DECODER_CHECKPOINT_PATH=checkpoints/s2-pro/codec.pth \
    -p 8080:8080 \
    fishaudio/fish-speech:server-cuda
Open http://localhost:8080/ui for the web interface, and check the server with:
curl -X GET http://127.0.0.1:8080/v1/healthIt should return {"status":"ok"}. If you expose it outside your network, start it with --api-key to require a token.
Without Docker, the docs use uv sync --python 3.12 --extra cu129 (or --extra cpu) after installing portaudio19-dev libsox-dev ffmpeg.
Clone a voice and generate audio through the API
The server stores reference voices under an ID. Upload a clean recording with its transcript:
curl -X POST http://127.0.0.1:8080/v1/references/add \
    -F id=my-voice \
    -F "audio=@reference.wav;type=audio/wav" \
    -F text="Exact transcript of the reference audio"
Then generate speech with that voice using the bundled client:
python tools/api_client.py --url http://127.0.0.1:8080/v1/tts \
    --text "Hi, this is my voice cloned locally." \
    --reference_id my-voice --format mp3 --output demo --no-play
Two time savers: the audio field needs its MIME type (;type=audio/wav) or the server can't read it, and --no-play avoids errors on servers without a sound card. The main endpoint is POST /v1/tts and the body is msgpack, not JSON, so use the client as a reference when calling it from your own code.
Emotions go inline: [whisper] This is a secret. [laughing] Just kidding.. With Drama 3, characters are separated with <|speaker:0|>, <|speaker:1|> and so on.
What it costs compared with ElevenLabs
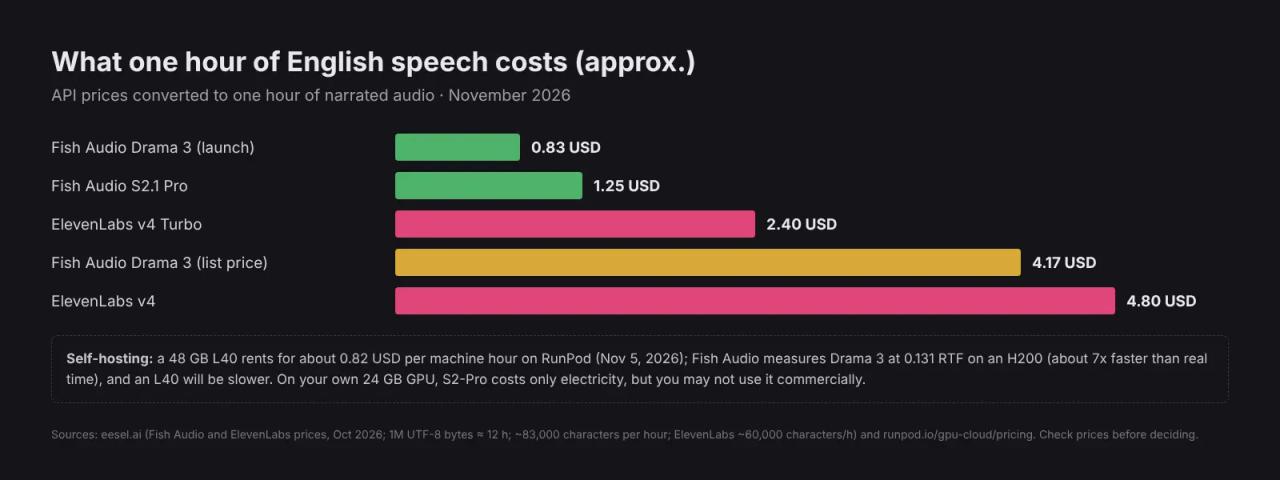
If you don't have a GPU, Fish Audio sells the same model as a service, and it is cheap. We converted public prices to one hour of narrated English audio:
| Option | Price | Approx. cost per hour of audio |
|---|---|---|
| Fish Audio Drama 3 (launch, until Nov 12, 2026) | 10 USD / million characters | 0.83 USD |
| Fish Audio S2.1 Pro | 15 USD / million UTF-8 bytes | 1.25 USD |
| ElevenLabs v4 Turbo | 0.04 USD / 1,000 characters | 2.40 USD |
| Fish Audio Drama 3 (list price) | 50 USD / million characters | 4.17 USD |
| ElevenLabs v4 | 0.08 USD / 1,000 characters | 4.80 USD |
Prices and conversions (1 million UTF-8 bytes ≈ 12 hours of speech): eesel.ai, October 2026. Accented characters take two bytes in UTF-8, so byte-billed plans cost a bit more in languages like Spanish or French.
The fish.audio web app also has a free plan with 8,000 credits a month (a few minutes of audio), Plus at 15 USD/month with 250,000 credits and Pro at 100 USD/month with 2 million.
Which option is cheapest for you
- Just testing or personal use: the fish.audio free plan or S2-Pro on your own 24 GB GPU. Zero cost.
- A few videos or ads a month for your business: the fish.audio API or Plus plan. You pay cents per minute and maintain nothing. Renting a 48 GB GPU, downloading tens of GB of weights and setting up the server doesn't pay off for a few minutes of audio.
- Hours of audio per week (audiobooks, long courses, dubbing), or text you can't send to a third party: self-hosted Drama 3 on a rented GPU you only switch on while generating, with free commercial use under 500,000 USD yearly revenue.
- You want to sell a voice service to others: you need a commercial license from Fish Audio. The Community License doesn't cover it.
If you want something with a simpler license, our VoiceStudio review covers engines with Apache-2.0 weights, such as Kokoro or VoxCPM2, that you can use commercially with no revenue thresholds.
Common errors
- Out of memory with Drama 3 on a 3090, 4090 or A6000. These cards are pre-SM89 or 24 GB: the FP8 experts get dequantized and the model doesn't fit. Use S2-Pro or an L40/L40S/H100, or split the model across GPUs with
--device cuda:0,cuda:1,.... --compilefails with Drama 3. It isn't supported; it only works with S2-Pro on Linux.- Silence, noise or "non-finite logits" on a V100. Pre-SM80 GPUs have no bfloat16, and the docs say the float16 path hasn't been tested on real hardware yet.
pyaudioinstall error. Installportaudio19-dev(orconda install pyaudio) and retry.- The cloned voice sounds off. Use a clean, single-speaker recording of 10 to 30 seconds, with a transcript that matches what you hear.
FAQ
Is Fish Speech free?
The code and models are free to download. Drama 3 can be used commercially at no cost while your yearly revenue is under 500,000 USD. S2-Pro is free only for personal use or research.
Does Fish Speech support languages other than English?
Yes. Both models cover more than 80 languages, including Spanish, French, German, Portuguese, Chinese and Japanese.
Can I use the generated voice in ads or a paid course?
With self-hosted Drama 3, yes, if you meet the revenue threshold, show "Built with Fish Audio" and the voice is yours or you have the person's permission. With self-hosted S2-Pro, no. With the fish.audio API, it depends on your paid plan's terms.
Does it run on a Mac or without a GPU?
S2-Pro runs on CPU, slowly. Drama 3 needs an NVIDIA GPU. Without a GPU, the practical option is the fish.audio API.
Conclusion
Fish Speech gives you a voice model that, by its own benchmarks, competes with ElevenLabs, under a license that allows free commercial use for small and mid-sized businesses. The rule for spending little is simple: the fish.audio API for low volumes, Drama 3 on a rented GPU when you generate hours of audio, and S2-Pro only for experiments. Before using it with clients, read the repository's LICENSE and get written permission from anyone whose voice you clone.
If you're putting that voice into videos, continue with OpenMontage for producing videos with Claude Code or HyperFrames, video from HTML.
// source code
// implementation
More on Open source tools
- Design, image and video
- Free alternatives to paid apps
- Free alternatives to paid apps
- Design, image and video
- Design, image and video
- Step-by-step tutorials